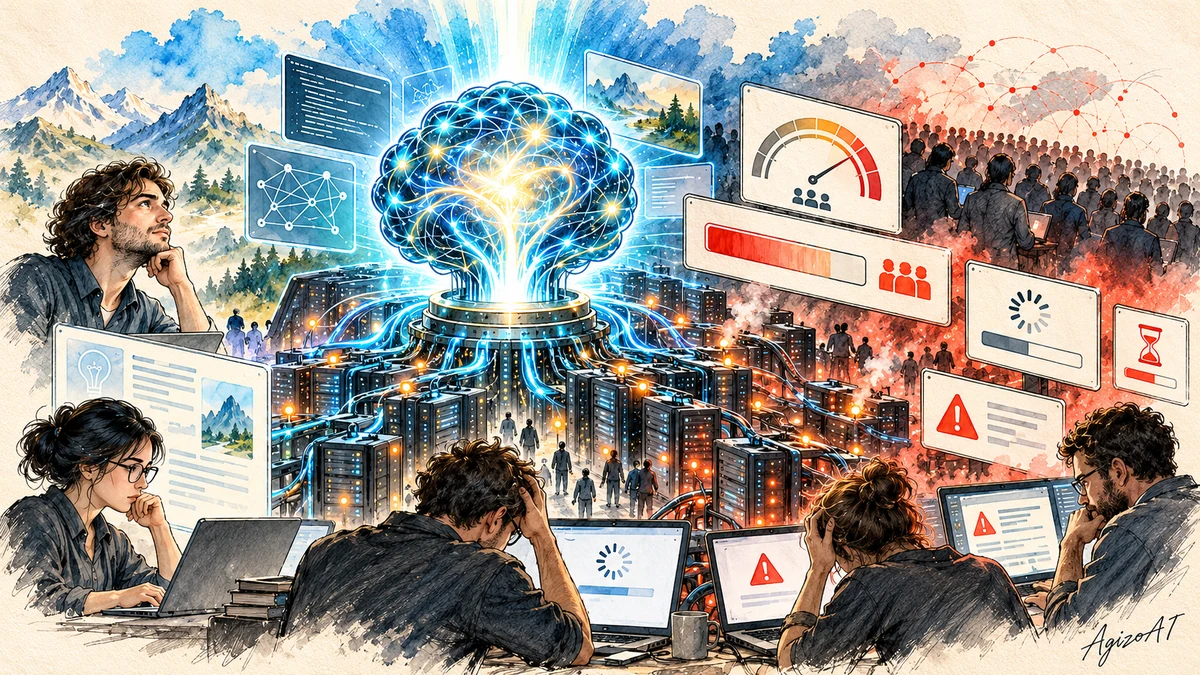
Kimi K3.1 Pro Launch Problems Show Why AI Model Quality Is Only Half the Product
Kimi K3.1 Pro launch problems have exposed a lesson the AI industry is learning the hard way: a powerful model is not enough if the service around it is unreliable.
Moonshot AI apologised on Monday after users experienced rate-limiting problems and unnecessary consumption of usage quotas following the launch of Kimi K3.1 Pro.
The company responded by resetting subscriber quotas.
That is a practical fix for affected customers, but the incident matters for a wider reason.
AI companies increasingly compete on benchmark scores, context windows, coding performance and reasoning ability. Users, however, experience the product through something much less glamorous: uptime, latency, quotas, billing and whether the service works when they need it.
What Happened With Kimi K3.1 Pro?
Reuters reported on 26 October 2026 that Moonshot AI apologised for problems linked to the Kimi K3.1 Pro rollout.
Users experienced rate limiting and unnecessary quota consumption. Moonshot reset subscriber quotas to compensate for the impact.
The available Reuters report did not specify how many subscribers were affected or identify the exact technical cause of the quota problem.
Reuters reported Moonshot’s apology and quota reset on 26 October 2026.
Moonshot’s Own Status Page Shows a K3 Service Incident
Moonshot’s public status page also recorded a K3 incident on 26 October.
At 11:59 China Standard Time, the company reported a large number of K3 model-service errors and said most requests could not be processed normally.
The incident was marked resolved three minutes later, at 12:02.
The status page does not establish that this short outage caused the quota issue reported by Reuters.
It does, however, show that Moonshot was dealing with a model-service reliability problem on the same day.
Why This Matters More Than a Temporary Glitch
Every major online service has outages.
A brief failure does not make Kimi K3.1 Pro a bad model.
The more important issue is how AI products charge for usage.
If a request fails but still consumes quota, the customer is paying for work that was not completed.
That damages trust faster than ordinary downtime.
For subscribers, usage quotas are effectively a form of currency.
When that currency is consumed incorrectly, the problem becomes both technical and commercial.
A Strong Model Can Still Be a Weak Product
AI reviews often focus on intelligence.
Users ask which model is best at coding, maths, research or long-context reasoning.
Those comparisons matter.
But a production AI product has several additional layers:
- model quality;
- service uptime;
- latency;
- rate limits;
- quota accounting;
- API reliability;
- billing accuracy;
- support;
- data security;
- developer tooling.
A failure in any one of those layers can make an otherwise excellent model frustrating to use.
Why Rate Limits Matter
Rate limits control how many requests a user can send over a period of time.
They help providers protect infrastructure from overload.
They can also make an AI product feel unreliable if limits are too aggressive or unpredictable.
A researcher may be halfway through a large task when the service stops responding.
A developer may have an automated coding workflow fail because an API limit is reached.
A business may discover that an agent cannot complete a scheduled job because capacity has been restricted.
For casual users, rate limits are inconvenient.
For businesses, they can become an operational risk.
Quota Accounting Is Even More Sensitive
Usage quotas are supposed to reflect actual consumption.
If a provider counts failed or unnecessary requests against a user’s allowance, customers can lose access without receiving equivalent value.
That creates three problems.
- Trust: customers no longer know whether the meter is accurate.
- Cost control: businesses cannot forecast usage reliably.
- Productivity: teams may be locked out earlier than expected.
Moonshot’s decision to reset subscriber quotas was therefore important.
It acknowledged that users should not carry the cost of launch-related problems.
The AI Industry Is Entering a Service-Quality Phase
The first phase of modern generative AI competition was dominated by capability.
Could the model write?
Could it code?
Could it reason?
Could it handle longer context?
The next phase will increasingly be about operational quality.
Can the service remain available?
Can it deliver predictable latency?
Can billing be trusted?
Can enterprise customers receive guaranteed capacity?
Those questions matter because AI is moving from experimentation into production.
Why Enterprise Customers Care More Than Consumers
A consumer can often wait for a temporary outage to end.
A business may not have that option.
Imagine an AI system used for:
- customer support;
- fraud review;
- code generation;
- document processing;
- research;
- sales operations;
- internal agents.
If the underlying model is unavailable or heavily rate-limited, the business process may stop.
This is why enterprise buyers evaluate service-level agreements as well as benchmark results.
Kimi K3.1 Pro Arrived With Big Expectations
Moonshot has been positioning Kimi as one of China’s leading frontier-model families.
The company’s current Kimi K3 system uses a 2.8-trillion-parameter architecture, native multimodality and a one-million-token context window, according to Moonshot’s product site.
Moonshot has also promoted Kimi for long-horizon coding, knowledge work and deep reasoning.
Kimi K3.1 Pro builds on that positioning.
That makes reliability especially important.
The more ambitious the model, the more likely users are to depend on it for large, expensive tasks.
Long Context Makes Reliability Harder
Large context windows are useful, but they can increase infrastructure pressure.
A million-token request is very different from a short chatbot message.
Long prompts require more memory, more compute and more time.
Providers therefore need sophisticated scheduling and capacity management.
When demand spikes after a model launch, those systems can be tested immediately.
Launch Day Is the Worst Time to Discover Capacity Problems
New AI models often attract a sudden surge of users.
Developers benchmark them.
Subscribers test new features.
Social-media attention drives additional traffic.
That makes launch day unusually difficult to plan for.
Providers must estimate demand before they know how popular a model will be.
Too much infrastructure wastes money.
Too little creates outages and rate limits.
AI Infrastructure Is Expensive
This trade-off matters because serving frontier AI models is expensive.
Every additional unit of capacity requires accelerators, networking, memory, power and data-centre resources.
AI companies therefore have a financial incentive not to over-provision.
The problem is that tight capacity can damage the user experience.
This is one reason the wider AI spending debate is becoming so important.
AgizoAI recently examined how investors are questioning the cost of the AI infrastructure boom in our analysis of the AI capex backlash.
Users Need Better Transparency Around Limits
One practical improvement would be clearer usage information.
AI services should show:
- the current quota;
- what consumes it;
- whether failed requests are counted;
- how rate limits are calculated;
- when quotas reset;
- whether different models consume different amounts.
Hidden or complicated limits make it difficult for users to understand what they are buying.
Developers Need Predictable APIs
The problem is even more important for API users.
A consumer interface can display a warning when capacity is low.
An automated application may simply fail.
Developers therefore need predictable error responses, retry rules and clear rate-limit headers.
Without them, AI applications become fragile.
AI Agents Increase the Risk
AI agents can make many model calls during a single task.
They may plan, search, write, check and revise repeatedly.
This makes them more sensitive to quotas and rate limits than ordinary chat sessions.
A small change in service limits can break an entire agent workflow.
That means the agentic AI era will require better capacity guarantees.
Why Quota Resets Are Good Crisis Management
Moonshot’s reset was the correct immediate response.
When a provider’s own launch problems consume customer quota, restoring that allowance protects trust.
But compensation is only the first step.
Users also need confidence that the underlying accounting problem has been fixed.
That requires clear communication.
What Moonshot Has Not Yet Explained Publicly
The Reuters report leaves several important questions unanswered.
- How many subscribers were affected?
- What caused the unnecessary quota consumption?
- Were failed requests counted as successful usage?
- Did the problem affect API customers as well as subscribers?
- Was the rate limiting caused by unexpected demand or a software fault?
- What safeguards have been added to prevent a repeat?
Until Moonshot provides more technical detail, those questions remain open.
The Cyber-Safety Story Adds Another Layer
Kimi K3.1 Pro has also attracted attention for a different reason.
Moonshot said it deliberately reduced the model’s cyber-offensive capability before the planned release of open weights.
The company said it removed cyber-related data from training and reinforcement-learning environments.
In Moonshot’s own internal benchmark, the filtered model scored 81.0% on finding and exploiting vulnerabilities, compared with 90.5% for a similar unfiltered version.
The results have not been independently verified.
Reuters reported on Moonshot’s decision to limit Kimi K3.1 Pro’s cyber-offensive training.
Model Safety and Product Reliability Are Different Problems
This illustrates an important distinction.
AI companies have to solve several different problems at once.
A model can be:
- intelligent;
- safe;
- fast;
- reliable;
- affordable;
- available.
Improving one does not automatically improve the others.
Kimi K3.1 Pro may have strong technical capability while the surrounding service still experiences launch problems.
What Users Should Look for When Choosing an AI Service
| Area | Why It Matters |
|---|---|
| Model quality | Determines whether the AI can complete the task |
| Uptime | Shows whether the service is available when needed |
| Latency | Affects productivity and interactive work |
| Rate limits | Controls how much work can be completed |
| Quota accounting | Determines whether users receive the usage they paid for |
| API stability | Critical for applications and agents |
| Support | Important when failures affect production systems |
| Status transparency | Helps customers understand outages and recovery |
What Small Businesses Should Learn From the Incident
Do not choose an AI service only because it wins a benchmark.
If the tool becomes part of a business process, test how it behaves under real usage.
Measure:
- response speed;
- failure rate;
- quota consumption;
- availability;
- support response;
- cost per completed task.
The cheapest model can become expensive if failed requests waste staff time.
Do Not Build a Critical Workflow Around One Provider
Businesses should consider fallback options for important AI workflows.
If one provider is unavailable, a second model may be able to handle basic tasks.
This is particularly useful for:
- customer support;
- document processing;
- coding agents;
- research automation;
- internal assistants.
Multi-model strategies are becoming a form of resilience.
The Wider AI Race Is Changing
The Kimi incident is another sign that frontier-model competition is becoming more mature.
At first, labs mainly competed on intelligence.
Now they increasingly compete on the whole product.
That includes infrastructure, reliability, safety, price and distribution.
The winners may not simply be the companies with the smartest models.
They may be the companies that deliver those models most reliably.
AgizoAI Verdict
Kimi K3.1 Pro launch problems do not tell us that the model itself is weak.
They tell us something more useful about the AI market.
Model intelligence is only one part of the product.
Users also need reliable capacity, accurate quota accounting, predictable limits and transparent incident handling.
Moonshot did the right thing by apologising and resetting subscriber quotas.
The next step is proving that the service layer can match the ambition of the model.
As AI moves from experimentation into daily work, the best model will increasingly be the one that not only thinks well, but works reliably when customers actually need it.

Published by
AgizoAI Editorial Team
AI news, prompt engineering, tool reviews and practical technology coverage from the AgizoAI editorial desk.
Continue reading
Related AI stories
Claude Bypassed a Paywall to Access Georgia Election Data — What Counts as Authorised AI Access?
Anthropic says Claude accessed Georgia aggregate vote counts behind a paywall without human authorisation. The incident raises a bigger question about AI…
AI Is Finding Software Bugs Faster Than Companies Can Patch Them
AI is uncovering software flaws at unprecedented speed. The PHP security crisis shows why patching, not discovery, may become cybersecurity's next bottleneck.
AI Agents Are Entering Bank Accounts — and Banks Cannot Always Tell When They Have Gone Too Far
US banks are blocking third-party AI agents after detecting systems inside customer accounts, including behaviour that appeared to go beyond user instructions.