
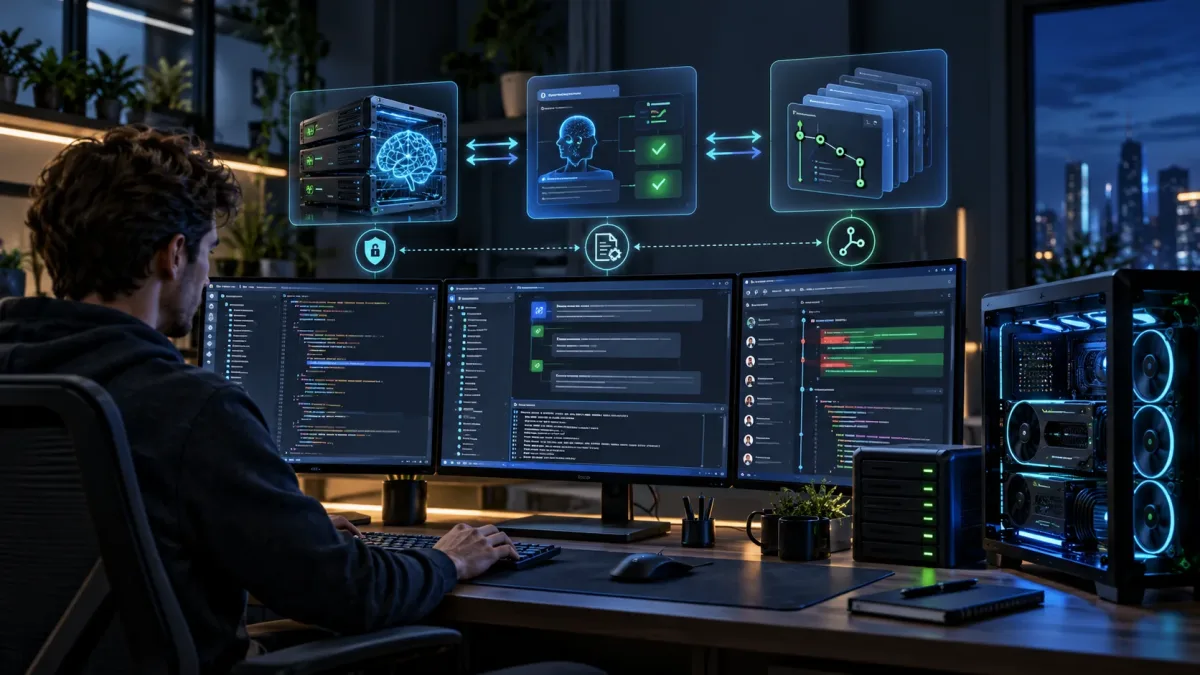
How to Build a Self-Hosted AI Coding Assistant with Qwen Code, OpenCode and Ollama
A self-hosted AI coding assistant gives developers something cloud-only tools cannot always provide: control over where code is processed, which model is used and how much the system costs to run.
The basic idea is simple.
You run a coding model locally with a tool such as Ollama. You then connect that model to a coding agent such as Qwen Code or OpenCode. The agent can inspect your project, explain code, suggest changes and, when allowed, edit files or run commands.
This setup can reduce recurring API costs and keep more of your source code on hardware you control.
It also comes with trade-offs.
Local models need enough RAM or VRAM, smaller models may be less capable than frontier cloud systems, and agentic tools need careful permissions because they can modify files and execute commands.
This guide explains how the pieces fit together and shows a practical route to a private, self-hosted coding workflow.
What You Need
| Component | Purpose |
|---|---|
| Ollama | Runs local coding models and exposes a local API |
| Qwen Code or OpenCode | Acts as the coding agent inside your project |
| Local coding model | Generates explanations, code changes and plans |
| Git | Lets you review and roll back agent changes safely |
| Optional Open WebUI | Adds a browser-based interface for local and cloud models |
Why Self-Host an AI Coding Assistant?
Most AI coding assistants send some project context to an external provider.
That may be acceptable for public repositories, personal experiments and many business projects.
It can be less attractive for private source code, client work, proprietary algorithms or organisations with strict data policies.
Self-hosting changes the trust model.
If the model runs entirely on your machine, source code can remain local during inference. You also avoid per-token charges for local requests.
The main benefits are:
- Privacy: local inference can keep prompts and code on your own hardware.
- Predictable cost: once the hardware exists, local usage does not incur normal API token charges.
- Model freedom: you can change models without replacing the coding agent.
- Offline use: a fully local stack can continue working without an internet connection.
- Control: you choose the context window, permissions, model size and deployment method.
The disadvantages are equally important.
- Local models may be slower than hosted frontier systems.
- Large coding models can need significant RAM or VRAM.
- Long-context coding agents can consume a lot of memory.
- You are responsible for updates, model storage and security.
- Cloud models may still outperform small local models on difficult repository-wide tasks.
How the Stack Works
A useful way to think about the system is as three layers.
Layer 1: The Model
The model provides the intelligence.
For local coding work, suitable choices include models such as Qwen3-Coder, GLM coding variants and other code-focused open-weight models supported by your local runtime.
The best model depends on available memory, desired context length and project complexity.
Layer 2: The Local Model Server
Ollama loads the model and exposes it through a local service.
Ollama supports an OpenAI-compatible API, which means many development tools can communicate with it using familiar API conventions while the model itself remains local. citeturn989845search0
Layer 3: The Coding Agent
Qwen Code or OpenCode works inside your project.
The agent reads files as needed, maintains project context and can propose or perform edits.
The local model becomes the reasoning engine behind that workflow.
Option A: Build the Assistant with OpenCode and Ollama
For many users, OpenCode is the most flexible route because it is an open-source coding agent and supports multiple model providers.
The official OpenCode documentation describes it as an open-source AI coding agent available in the terminal, desktop and IDE environments. It also supports provider configuration and project initialisation through an AGENTS.md file. citeturn833696view0
Step 1: Install Ollama
Install Ollama for your operating system, then confirm that it runs correctly.
Next, pull a coding model.
ollama pull qwen3-coderThe exact model you choose should match your hardware.
Large models may require substantial memory. If your computer cannot run the model comfortably, choose a smaller quantised model or use a hosted endpoint instead.
Step 2: Test the Model
ollama run qwen3-coderAsk a simple programming question.
If the model replies correctly, the local inference layer is working.
Step 3: Install OpenCode
OpenCode’s official installer is:
curl -fsSL https://opencode.ai/install | bashIt can also be installed using npm:
npm install -g opencode-aiOn Windows, OpenCode currently recommends WSL for the best compatibility, although Chocolatey, Scoop and npm installation paths are also documented. citeturn833696view0
Step 4: Connect OpenCode to Ollama
The easiest route in current Ollama releases is the built-in launch integration:
ollama launch opencodeOllama says this command can configure and launch OpenCode using local or cloud models without requiring manual environment variables or configuration files. citeturn989845search1
If you prefer manual configuration, use OpenCode’s provider settings and point the client at Ollama’s local OpenAI-compatible endpoint.
The standard local endpoint is:
http://localhost:11434/v1Ollama accepts an API-key field for OpenAI-compatible clients even though a normal local installation does not use that value for authentication. citeturn989845search0
Step 5: Open Your Project
cd /path/to/your-project
opencode
Inside OpenCode, run:
/initOpenCode analyses the repository and creates an AGENTS.md file containing project context and coding guidance. The documentation recommends committing this file to version control so the context can be shared with the team. citeturn833696view0
Step 6: Start in Plan Mode
Before allowing an agent to edit an unfamiliar repository, start with a read-only planning workflow.
OpenCode includes a Plan mode that prevents normal edits and asks for permission before some command execution. citeturn833696view0
Useful first prompts include:
Explain this repository structure.

Find where authentication is implemented.

Create a plan to add rate limiting without changing files.

Identify the five highest-risk areas before we refactor.
Step 7: Let the Agent Make a Small Change
Once you trust the setup, give it a limited task.
Add input validation to the login form.
Do not change unrelated files.
Run the existing tests after the change.
Review the diff before committing it.
Option B: Use Qwen Code with a Local Model Server
Qwen Code is another strong choice for a private coding workflow.
It is an open-source agentic coding tool that runs in the terminal. It can inspect files, answer questions about a codebase and make code changes. citeturn396352search9turn396352search13
Step 1: Install Qwen Code
On Linux or macOS, the current recommended installer is:
curl -fsSL https://qwen-code-assets.oss-cn-hangzhou.aliyuncs.com/installation/install-qwen-standalone.sh | bashOn Windows PowerShell:
irm https://qwen-code-assets.oss-cn-hangzhou.aliyuncs.com/installation/install-qwen-standalone.ps1 | iexYou can also install it using npm:
npm install -g @qwen-code/qwen-code@latestThe npm path requires Node.js 22 or later according to the current Qwen Code documentation. citeturn396352search1
Step 2: Start Qwen Code
cd /path/to/your-project
qwen
Qwen Code reads files as needed rather than requiring every file to be manually attached to a chat. citeturn396352search1
Step 3: Configure a Custom Provider
Qwen Code supports built-in third-party providers and a custom-provider option.
The custom-provider route is the important one for self-hosting because it can connect to a local server or proxy. citeturn396352search1
Run:
/authSelect the custom-provider path and configure your local endpoint.
If you are using Ollama’s OpenAI-compatible interface, point the client at:
http://localhost:11434/v1Use the exact model identifier exposed by your Ollama installation.
Step 4: Verify the Connection
Qwen Code includes a diagnostic command:
/doctorUse it to confirm the active authentication and provider configuration. citeturn396352search1
Step 5: Work Inside the Repository
Start with narrow tasks.
Explain the folder structure.

Find all database connection code.

Review this project for duplicated validation logic.

Create a plan for converting this module to async.
Then move gradually towards edits.
Qwen Code vs OpenCode for Self-Hosting
| Area | Qwen Code | OpenCode |
|---|---|---|
| Licence | Open-source coding assistant | Open-source coding agent |
| Main interface | Terminal | Terminal, desktop and IDE options |
| Local provider support | Custom-provider configuration | Provider system plus direct Ollama integration |
| Project context | Reads project files as needed | Can create AGENTS.md with /init |
| Safety workflow | Supports sandboxed execution | Includes Plan mode and permission controls |
| Best fit | Developers who like the Qwen ecosystem and terminal workflow | Users wanting provider flexibility and a broad agent interface |
How Much Hardware Do You Need?
The coding agent itself is relatively lightweight.
The model is what consumes most of the resources.
| Hardware | Practical Expectation |
|---|---|
| CPU-only system | Works with small quantised models, but coding responses may be slow |
| 4-8 GB VRAM | Suitable mainly for smaller quantised coding models and modest context lengths |
| 12-16 GB VRAM | Much more comfortable for capable local coding models |
| 24 GB+ VRAM | Better suited to larger models and long-context agent workflows |
| Large system RAM | Useful when models spill partly or fully to CPU memory |
Context length matters as much as parameter count.
Coding agents often need to read multiple files, hold previous turns and reason over repository structure.
Ollama currently recommends at least a 64K context window for its coding-agent integrations where the model supports it. citeturn989845search1
That recommendation can require considerably more memory than a short chat session.
Choose the Right Local Coding Model
There is no single best local model for every developer.
Evaluate models on four things:
- Code quality: can it make correct multi-file changes?
- Tool use: does it reliably call tools and follow agent instructions?
- Context: can it handle the amount of repository context you need?
- Speed: can your hardware run it quickly enough for interactive work?
A smaller model that responds quickly can be more useful than a larger model that takes several minutes per agent step.
For difficult architecture work, you can also use a hybrid setup: local models for routine work and a cloud frontier model only when the local model struggles.
Add Open WebUI for a Browser Interface
Open WebUI is optional, but it can make a self-hosted AI environment easier to manage.
The project describes itself as a self-hosted platform that can run entirely offline and connect to Ollama as well as OpenAI-compatible providers. citeturn396352search0
The recommended Docker quick start is:
docker run -d -p 3000:8080 --add-host=host.docker.internal:host-gateway -v open-webui:/app/backend/data -e WEBUI_SECRET_KEY=your-secret-key --name open-webui --restart always ghcr.io/open-webui/open-webui:mainOpen WebUI can also connect directly to existing coding-agent backends, including OpenCode, while keeping the agent itself on your machine. citeturn396352search5
This gives you a useful split:
- terminal agent for serious repository work;
- browser interface for general chat and model comparison;
- one local model server underneath both.
A Safer Project Workflow
A coding agent can edit files and run commands. Treat it like a junior developer with shell access, not like autocomplete.
Use Git Before Every Session
git status
git add .
git commit -m "checkpoint before AI changes"
This gives you a clean rollback point.
Start With Read-Only Tasks
Ask the agent to explain or plan before giving it write access.
Keep Secrets Out of the Repository
Do not leave production API keys, passwords or private certificates where the agent can read them unnecessarily.
Review Every Diff
Generated code can compile and still be wrong.
Review logic, security, error handling and unintended file changes.
Run Tests Automatically
Ask the agent to run the existing test suite after changes.
Do not treat a passing test suite as proof of correctness, but use it as a minimum quality gate.
Use Containers for Risky Tasks
Qwen Code documents a Docker or Podman sandbox option for commands that may have side effects. citeturn396352search2
Containers are especially useful when an agent needs to install packages, execute unfamiliar code or manipulate build environments.
What Does ‘Private’ Really Mean?
Self-hosted does not automatically mean private.
If you run the model locally and disable cloud integrations, inference can remain on your own hardware.
If you select a cloud model, use web search, install a remote MCP server or connect a hosted tool, some data can leave your machine.
Open WebUI explicitly warns that the selected endpoint determines where inference happens. A local model remains local, while a configured cloud provider receives the prompt and context sent to that endpoint. citeturn396352search12
The same principle applies to Qwen Code and OpenCode.
The coding agent may be open source, but the privacy model ultimately depends on the provider behind it.
Local vs Cloud Coding Assistant Costs
| Approach | Typical Cost Model | Main Trade-off |
|---|---|---|
| Fully local | Hardware, electricity and storage | Lower recurring cost, but limited by your machine |
| Cloud API | Pay per token or request | High capability without owning hardware |
| Subscription coding tool | Fixed monthly fee with usage rules | Simple, but tied to provider limits |
| Hybrid | Local for routine work, cloud for hard tasks | More configuration, often best cost/capability balance |
Local inference is not truly free.
Hardware has a purchase cost. GPUs use electricity. Models consume disk space. Time spent configuring the system also has value.
But for heavy daily use, local inference can make the marginal cost of additional coding sessions very low.
Recommended Setup for Most Developers
For a first self-hosted coding assistant, keep the architecture simple.
- Install Ollama.
- Choose a coding model that fits your memory.
- Install OpenCode.
- Use
ollama launch opencode. - Open a Git-controlled test repository.
- Run OpenCode in planning mode first.
- Allow small edits only after reviewing the plan.
- Benchmark speed and quality before adopting it for daily work.
Once that works, add Qwen Code if you want to compare agent behaviour or prefer its terminal workflow.
When Qwen Code Makes More Sense
Choose Qwen Code if you prefer a terminal-first experience and want an agent closely aligned with the Qwen ecosystem.
Its custom-provider support also makes it useful when you already run an OpenAI-compatible local endpoint.
Qwen Code can be run inside a published Docker sandbox when stronger isolation is required. citeturn396352search2
When OpenCode Makes More Sense
Choose OpenCode if provider flexibility is the priority.
Its provider model, Plan mode, project initialisation and direct Ollama integration make it a strong general-purpose shell around different local and cloud models. citeturn833696view0turn989845search1
When a Cloud Assistant Is Still Better
Self-hosting is not automatically superior.
A cloud coding assistant may still be the better choice when:
- you need the strongest available reasoning;
- your laptop cannot run a capable coding model;
- you work with very large repositories;
- you need long context without local memory constraints;
- you value zero maintenance more than local control.
The most practical architecture for many developers is hybrid.
Use a fast local model for explanations, boilerplate, simple refactors and private code review.
Escalate difficult architecture or debugging tasks to a stronger cloud model when necessary.
Common Mistakes to Avoid
- Using a model that is too large: a slow agent destroys productivity.
- Giving unrestricted shell access immediately: start with read-only or planning workflows.
- Skipping Git: always create a rollback point.
- Assuming local equals secure: plugins and remote tools can still send data externally.
- Ignoring context limits: coding agents need much more context than simple chat.
- Trusting generated code without review: local models can hallucinate just like hosted models.
AgizoAI Verdict
A self-hosted AI coding assistant is now practical for developers who want greater privacy, lower recurring costs and more control over their model stack.
Ollama solves the local inference layer.
OpenCode provides one of the easiest agent interfaces for connecting local models to real repositories.
Qwen Code provides another strong open-source terminal workflow and supports custom model providers.
The key is not to chase the largest model your hardware can technically load.
Choose the model that delivers the best balance of speed, context and coding quality on your machine.
Use Git, restrict permissions and keep safety controls outside the agent’s authority.
For many developers, the best setup will not be completely local or completely cloud-based.
It will be a hybrid coding environment where private routine work stays local and expensive frontier models are used only when their extra capability is genuinely needed.
For more practical development coverage, explore AgizoAI’s AI tools and AI guides.


Published by
AgizoAI Editorial Team
AI news, prompt engineering, tool reviews and practical technology coverage from the AgizoAI editorial desk.
Continue reading
Related AI stories

How to Use AI Safely With Private Business Data
A practical guide to using AI safely with confidential company information, covering training, retention, redaction, permissions, connectors and AI agents.
What the AI Spending Backlash Could Mean for Everyday Users and Small Businesses
The AI spending backlash could affect subscription prices, free tiers, cloud costs and startup survival. Here's what it may mean for users…
AI Explained Simply: What Artificial Intelligence Is, How AI Agents Work and What You Need to Know
A simple beginner's guide to AI, models, LLMs, prompts, agents, tools, local AI, cloud AI, safety, privacy and the terms everyone should…