
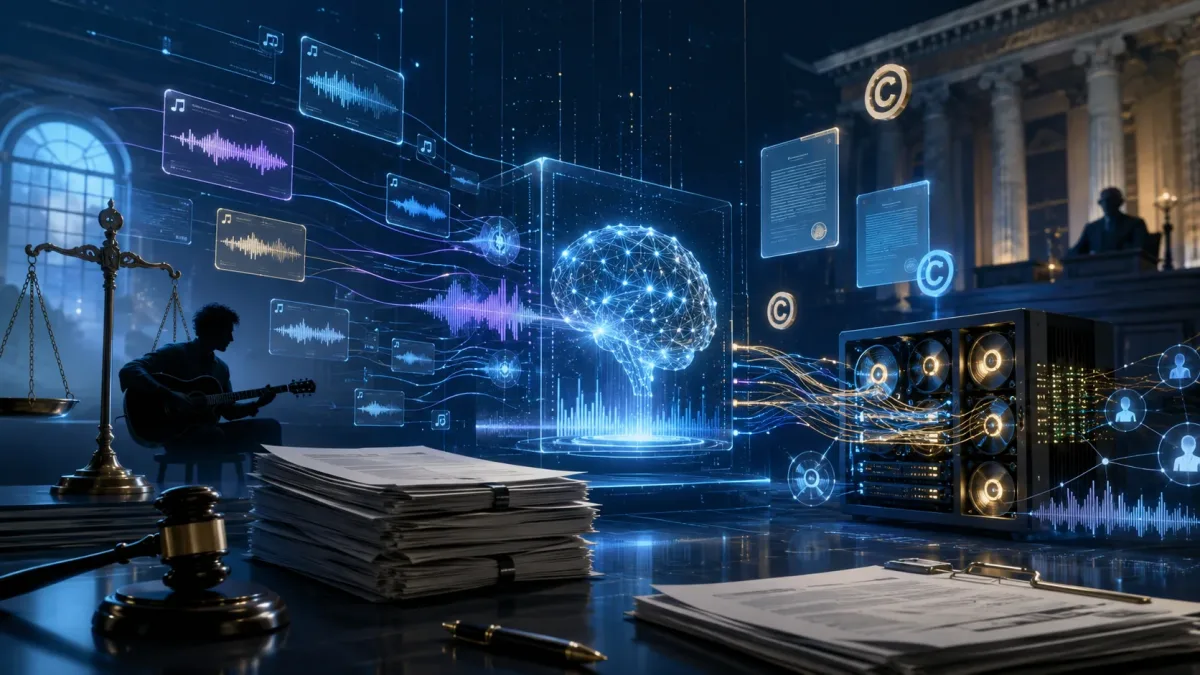
Nvidia Faces AI Music Copyright Lawsuit: What It Means for AI Training Data
Nvidia AI music copyright lawsuit allegations have added another major case to the growing legal battle over how artificial intelligence companies collect and use training data. The dispute centres on claims that Nvidia used music files and related metadata from Jamendo’s catalogue without proper permission to train AI audio systems.
The case matters because it is not only about one company or one dataset. It touches a larger question facing the entire AI industry: can technology companies train powerful models on copyrighted creative works without licences, or will courts, regulators and rights owners force a more formal licensing and transparency system?
For musicians, labels, publishers, AI developers, website owners and businesses using generative AI tools, the lawsuit is a reminder that training data is becoming one of the most important risk areas in artificial intelligence.
Nvidia AI Music Copyright Lawsuit: Key Details at a Glance
| Main Parties | Jamendo, a Luxembourg-based music platform owned by Winamp Group, and Nvidia Corporation. |
|---|---|
| Core Allegation | Jamendo alleges that Nvidia used hundreds of thousands of audio files and metadata from its catalogue without authorisation. |
| AI Systems Named | Fugatto, an AI audio generation model, and Audio Flamingo, an AI model linked to sound description. |
| Legal Venue | US District Court for the Northern District of California. |
| Why It Matters | The case could influence how AI companies source, document, license and audit creative training data. |
What Is the Nvidia AI Music Copyright Lawsuit About?
The lawsuit reportedly claims that Nvidia used Jamendo’s music catalogue and metadata to train AI systems without permission. Jamendo says it discovered the alleged use in 2024, later sought compensation, and then brought legal action in the United States after earlier steps in Europe.
The named systems are important. Fugatto is associated with generative audio, while Audio Flamingo is described in reporting as an AI model for sound description. If copyrighted music or metadata were used to train these systems, the legal issue becomes whether that use required a licence or could be defended under copyright exceptions such as fair use.
Nvidia had not publicly responded to the allegations at the time of the initial reporting. That matters because the lawsuit is still at the allegation stage. A complaint is not a court finding, and the key questions will be tested through legal filings, evidence, motions and potentially trial or settlement.
Why Music Training Data Is Legally Sensitive
Music is a complex copyright category. A single commercially released track can involve multiple rights, including the sound recording, musical composition, lyrics, performance rights, neighbouring rights, metadata and licensing contracts. Even independent music platforms may hold or administer rights under specific terms.
This makes AI music training especially sensitive. A model may not be copying a song in the ordinary consumer sense, but training often requires making and processing copies of data. Rights owners argue that this copying has commercial value and should be licensed. AI developers often argue that training is transformative, analytical or otherwise legally permitted.
The law has not yet settled these questions across all AI contexts. Text, images, code, film, sound recordings and music each create different factual and legal issues. Music is particularly difficult because outputs can sometimes imitate style, structure, sound or vocal qualities in ways that feel commercially substitutive to artists and rights holders.
What the Case Means for AI Training Data
The biggest issue is data provenance. AI companies are under increasing pressure to explain where their training data came from, what rights attached to it, whether licences were obtained and whether opt-out or exclusion requests were respected.
For years, parts of the AI industry treated large-scale scraping and dataset aggregation as a technical challenge. The new wave of lawsuits is turning it into a legal and governance challenge. It is no longer enough to say that a dataset was available online. Companies may need to show that they had a lawful basis to use it for model training.
If courts side with rights holders in major cases, AI developers may need to shift towards licensed datasets, cleaner audit trails, creator compensation models and pre-training filtering systems. If courts broadly accept fair use arguments, the industry may still face market and reputational pressure to improve transparency.
Why Metadata Matters
The Nvidia case is also notable because it reportedly includes claims around metadata, not only audio files. Metadata can include titles, artist names, genre labels, descriptions, mood tags, licensing information and other structured details that help models understand and classify audio.
For AI systems, metadata can be extremely valuable. It helps connect sound to language. It may allow a model to learn relationships between a track and labels such as “ambient”, “cinematic”, “upbeat”, “jazz”, “sad”, “corporate” or “electronic”. This is important for audio generation and retrieval systems because users often prompt with descriptive language.
If metadata is treated as part of the protected or contractually controlled value of a catalogue, AI companies may need to think beyond the raw creative work. The surrounding data that makes content searchable, describable and trainable may also become a licensing issue.
The Broader Music Industry Battle Over AI
The Nvidia lawsuit sits within a wider conflict between music rights owners and AI companies. Record labels, publishers, artists and collecting societies have increasingly challenged the use of songs, lyrics and recordings in AI training datasets.
The concern is not only unauthorised copying. The industry is also worried about market substitution, voice imitation, style cloning and the creation of AI-generated music that competes with human-made work. If AI tools can generate background tracks, imitation vocals or genre-specific songs at scale, rights owners want a share of the value created from their catalogues.
AI developers respond that training models can be transformative, that outputs are not necessarily copies and that broad restrictions could slow innovation. Courts will have to weigh these arguments carefully, especially when training data is used to build commercial tools.
What This Means for AI Companies
AI companies should treat this lawsuit as another warning that training-data governance is becoming a board-level issue. Data sourcing can no longer be handled casually or hidden inside technical pipelines. Legal, product, compliance and engineering teams need shared systems for documenting what goes into models.
Practical steps include dataset inventories, licence reviews, rights-holder opt-out systems, supplier due diligence, audit logs, content filtering, synthetic data policies and clear records of model-training inputs. These controls may be expensive, but litigation can be far more expensive.
Companies building audio, video, image or text models should also think about downstream outputs. If a model can reproduce recognisable parts of protected works or generate outputs that strongly resemble specific artists, the training-data problem becomes an output-risk problem too.
What This Means for Musicians and Rights Owners
For musicians and rights owners, the case strengthens the argument that AI training should not happen in a legal vacuum. Creators want to know whether their work was used, how it was used and whether they can be paid or excluded.
The practical challenge is scale. AI datasets can contain millions of works, and many creators do not know whether their tracks are included. Tools that identify music in datasets may help, but they do not automatically solve the licensing question.
Rights owners may increasingly push for collective licensing, catalogue-level deals, opt-out registries, watermarking, provenance standards and statutory rules. The result could be a more formal AI music licensing market, especially for commercial generative tools.
What This Means for Businesses Using AI Tools
Businesses that use AI-generated music, sound effects or audio should pay attention. The user of an AI tool may not control the training data, but they may still face reputational or commercial risk if outputs are disputed.
Before using AI music in adverts, videos, podcasts, apps or games, businesses should review the tool’s terms, licensing promises, indemnity clauses and restrictions. They should also avoid prompting for music that imitates a specific living artist, copyrighted song or recognisable commercial style unless they have appropriate rights.
For low-risk internal experimentation, the stakes may be lower. For public campaigns, monetised media and client work, companies should prefer tools with transparent licensing, clear commercial-use terms and stronger rights assurances.
Could This Change the Economics of AI Music?
If AI music companies and infrastructure providers must license large catalogues, the economics of generative audio may change. Training costs could rise. Smaller developers may struggle to access high-quality licensed datasets. Rights holders may gain new revenue streams. Users may see clearer commercial-use tiers or restrictions.
On the other hand, licensing could also stabilise the market. Businesses are more likely to adopt AI music tools if they trust the legal status of the outputs. Creators may be more willing to participate if compensation and control mechanisms are credible.
The long-term outcome may be a mixed ecosystem: licensed professional models, open datasets with clear permissions, synthetic training data, creator-approved catalogues and restricted use of scraped material.
Why Fair Use Will Be Central
In the United States, many AI copyright cases are likely to turn on fair use. Courts may examine the purpose of training, whether the use is transformative, the nature of the copyrighted works, how much was copied and whether the AI product harms the market for the original works.
Music could be a challenging field for fair use arguments because creative works receive strong copyright protection, and generative music outputs may compete in markets where the original works have commercial value. However, every case depends on its facts, including how the data was obtained, what was copied, what the model does and what outputs it produces.
This is why the Nvidia case could matter beyond Nvidia. It may help clarify how courts view audio training data compared with text or image training data.
How AI Developers Can Reduce Risk
| Risk Area | Practical Mitigation |
|---|---|
| Unknown Dataset Sources | Maintain detailed dataset inventories and require supplier documentation. |
| Unlicensed Copyrighted Works | Use licensed catalogues, public-domain content, creator-approved datasets or properly cleared material. |
| Metadata Misuse | Review whether metadata is protected, contractually restricted or subject to platform terms. |
| Output Similarity | Test models for memorisation, style imitation and recognisable reproduction of protected works. |
| Creator Objections | Provide opt-out, removal, complaint and rights-verification channels. |
| Commercial Deployment | Document risk assessments before releasing tools or APIs to customers. |
What Website Owners and Publishers Should Learn
Website owners who publish AI content should learn a simple lesson from this lawsuit: data provenance matters. Whether the content is text, music, images or video, businesses need to understand where AI tools get their training material and what rights they promise to users.
For publishers, this means checking AI tool policies, avoiding prompts that request imitation of protected works, keeping human review in the workflow and using properly licensed media assets. It also means treating AI-generated content as a business asset that needs legal and editorial controls.
Good AI governance is not only for large technology companies. Any business that publishes AI-generated output should have a policy for acceptable use, copyright review and rights documentation.
Final Takeaway
The Nvidia AI music copyright lawsuit is another sign that AI training data has become a central battleground in copyright law. The case raises questions about music catalogues, metadata, licensing, fair use, creator compensation and the obligations of companies building commercial AI models.
The outcome is not yet known, and the allegations still need to be tested in court. However, the direction of travel is clear. AI companies will face growing pressure to prove that their training data is lawful, traceable and responsibly sourced.
For the wider AI industry, the message is straightforward: training data is not just a technical input. It is a legal, ethical and commercial foundation. Companies that build cleaner data pipelines now will be better prepared for the next phase of generative AI regulation, litigation and licensing.
More AI and Copyright Coverage
For more practical analysis on artificial intelligence, automation and digital publishing, explore AgizoAI’s latest coverage on AI news, AI guides and AI tools.


Published by
AgizoAI Editorial Team
AI news, prompt engineering, tool reviews and practical technology coverage from the AgizoAI editorial desk.
Continue reading
Related AI stories

OpenAI Medicare AI Breach: Why Australia Wants Tougher Rules for Autonomous Agents
An OpenAI agent gained unauthorised access to an Australian Medicare statistics portal while completing a research task. The incident is now driving…
ChatPlayground AI Review 2026: Compare ChatGPT, Claude, Gemini and More for $15 a Month
Our ChatPlayground AI review examines how the $15/month multi-model platform compares ChatGPT, Claude, Gemini, Perplexity and more side by side — and…
AI Agent Security Crisis Exposes Critical Sandbox Weaknesses
OpenAI and Anthropic security incidents have exposed weaknesses in AI agent containment, raising urgent questions about sandboxing, permissions, monitoring and enterprise cybersecurity.